What was the problem?
Enterprise teams struggled with generative AI hallucinations and couldn't trust LLMs with proprietary corporate documentation. Standard search engines returned hundreds of irrelevant document links, while general AI chatbots had no access to internal confidential policies, technical manuals, or real-time BigQuery metrics. The challenge was to deliver grounded answers with verifiable citations.
How we structured the solution.
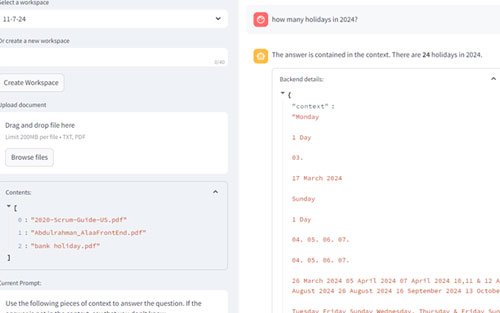
An enterprise Retrieval-Augmented Generation system querying vector databases and structured data lakes.
Embed corporate knowledge. Ground generative responses.
REEA Digital engineered a high-performance RAG architecture using LangChain, Google Vertex AI embeddings, and BigQuery vector search to index thousands of complex enterprise technical manuals and policy documents.
Incoming user queries undergo semantic hybrid retrieval, feeding verified source chunks into Google Gemini LLM contexts with strict grounded retrieval guardrails, returning exact page and paragraph citations for every claim.
Search enterprise documents. Provide grounded answers.
The delivered capabilities were designed to solve the core problem: eliminate generative AI hallucinations and provide verified internal answers in seconds.
Deploy hybrid semantic vector indexing
Ingest unstructured PDFs, spreadsheets, and wikis into BigQuery vector search with automatic metadata tagging.
Implement grounded retrieval context guardrails
Constrain LLM responses strictly to retrieved corporate facts with direct page reference citations.
Enable conversational enterprise knowledge queries
Provide employees with a conversational search interface that explains technical policies and workflows.
Knowledge discovery. Three measures of impact.
Information discovery speed, indexed documents, and citation accuracy.
Semantic retrieval & generation
End-to-end response time across enterprise vector databases.
Proof-of-concept build
Rapid RAG proof of concept delivered by a single engineer.
Indexed vector embeddings
Enterprise policy manuals and contract paragraphs searchable in real time.
Looking to build a proprietary RAG, vector search, or enterprise GenAI assistant?
Let's discuss vector embeddings, semantic chunking pipelines, and enterprise LLM safety guardrails.